Most tutorial Retrieval-Augmented Generation (RAG) demos follow a deceptively simplistic script: load a PDF with PyPDF, chunk it naively by character length, pass it to an in-memory vector store, and prompt an LLM with the top-3 chunks. When teams attempt to deploy this pattern into enterprise production, it invariably breaks: complex tabular financials are mangled, domain-specific acronyms disappear from dense vector embeddings, long documents trigger context overflow, and operators have zero visibility into citation provenance or query latencies.
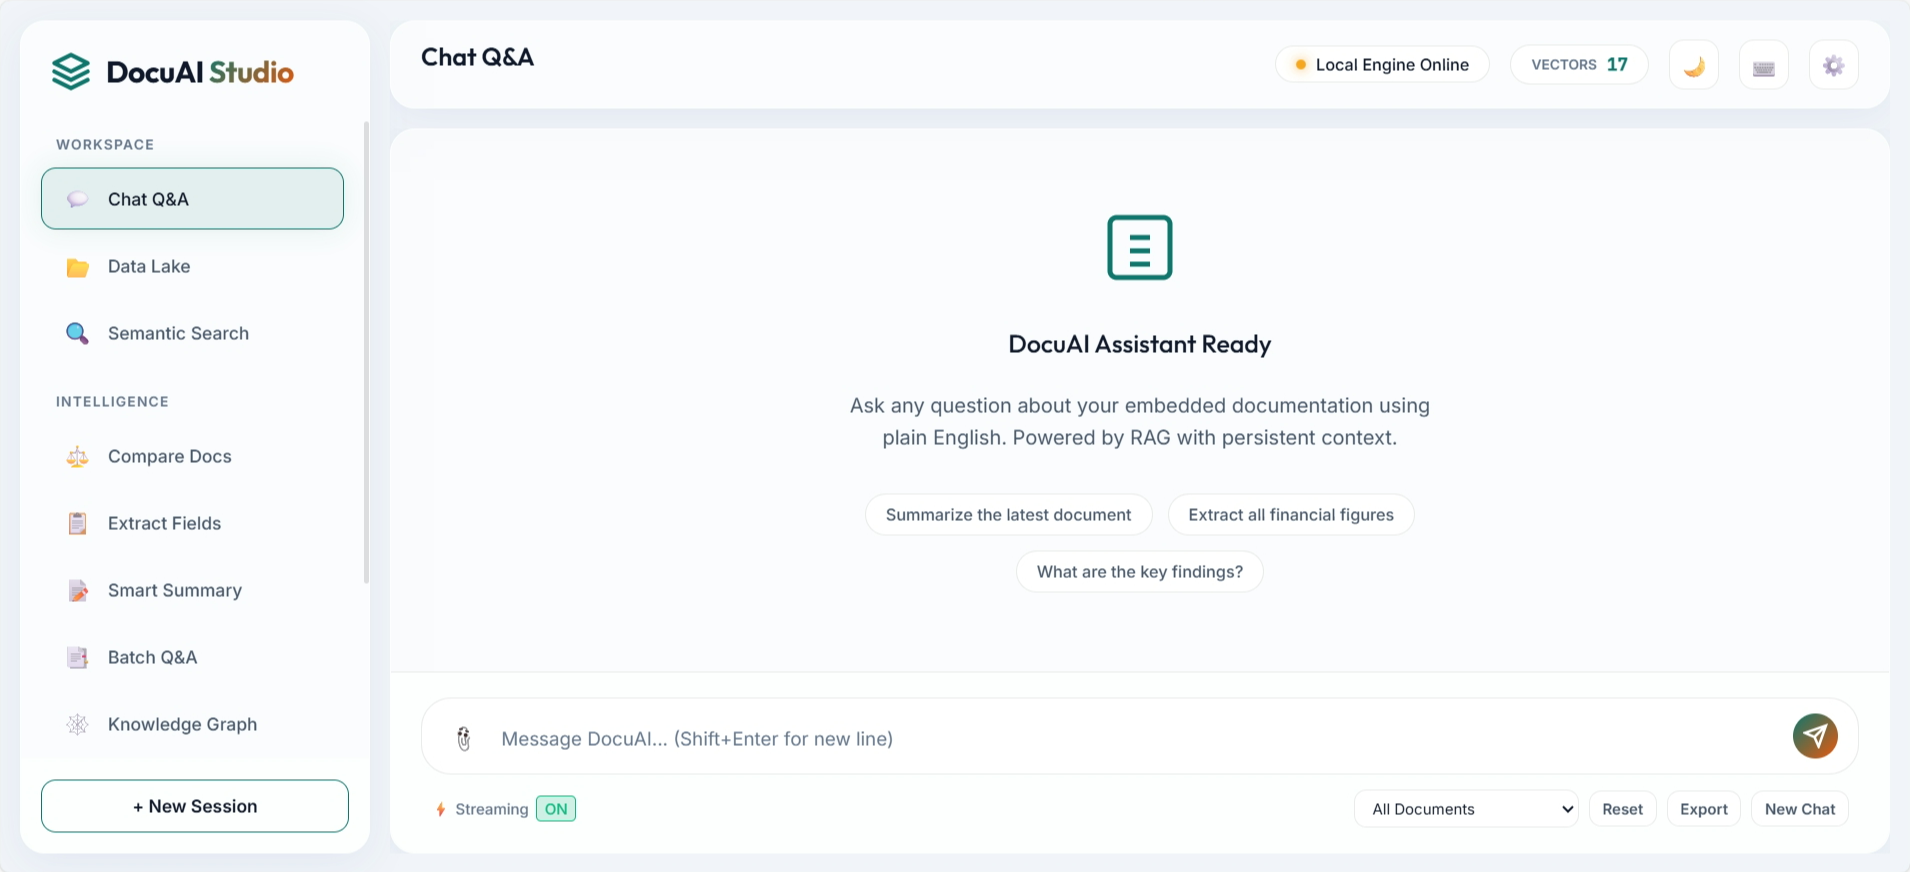
DocuAI Studio v3.1 was engineered to bridge this gap between toy prototypes and industrial reality. It is a full-stack, local-first Document AI platform capable of ingesting PDFs, Word documents, Excel sheets, presentations, scanned OCR images, and live web URLs. By combining dual-track sparse (BM25) and dense (FAISS) retrieval with Reciprocal Rank Fusion (RRF) and cross-encoder re-ranking, DocuAI achieves strict factual grounding and sub-second token streaming across 40+ modular FastAPI endpoints.
1. The Production RAG Gap: Why Naive Pipelines Fail
Before examining the code, it is critical to analyze why conventional single-vector retrieval fails on real-world enterprise corpora:
- The Semantic Blind Spot on Specific Tokens: A dense bi-encoder like
all-MiniLM-L6-v2maps semantic concepts effectively (e.g. understanding that "revenue decline" relates to "loss in earnings"), but completely fails on precise lexical identifiers like invoice codeINV-2024-998Aor part numberX49-B. - Loss of Tabular Geometries: Extracting text from complex multi-page financial balance sheets using standard text dumpers strips row-column spatial relationships, producing nonsensical token streams that hallucinate numerical correlations.
- Context Window Contamination: Passing 10 unranked chunks to an LLM dilutes attention. The "lost-in-the-middle" effect causes models to overlook critical clauses tucked into middle chunks.
High-precision RAG requires a three-tier retrieval cascade: high-recall hybrid retrieval (Dense + Sparse), algorithmic fusion (RRF), and a deep Cross-Encoder reranking pass to ensure only the top factual nuggets reach generation context.
2. Layered System Architecture
DocuAI Studio v3.1 separates concern into five strictly decoupled layers: Ingestion & Parsing, Vector & Lexical Indexing, Hybrid Retrieval Cascade, Generation & Guardrails, and WebSocket Streaming Delivery:
DocuAI Studio Ingestion to Generation Flow
- STAGE 01 Multi-Modal Parse PDF, OCR, XLSX, DOCX, Web scraper
- STAGE 02 Semantic Chunker Header-aware recursive splitting with overlap
- STAGE 03 Dual Indexing FAISS FlatL2 (384D) + BM25 Okapi corpus
- STAGE 04 RRF Fusion Reciprocal Rank Fusion k=60 merging
- STAGE 05 Cross-Encoder bge-reranker-base scoring top-5 chunks
- STAGE 06 Stream Response SSE / WebSocket with inline citation spans
3. Hybrid RRF & Cross-Encoder Implementation
The bedrock of DocuAI's precision is the hybrid retrieval coordinator. Dense search handles semantic paraphrasing, BM25 catches exact keyword matches, and Reciprocal Rank Fusion normalizes their score distributions without requiring arbitrary multiplier tuning:
import numpy as np
from typing import List, Dict, Any
from rank_bm25 import BM25Okapi
import faiss
from sentence_transformers import CrossEncoder

class ProductionHybridRetriever:
    def __init__(self, embed_dim: int = 384, rrf_k: int = 60):
        self.embed_dim = embed_dim
        self.rrf_k = rrf_k
        self.dense_index = faiss.IndexFlatIP(embed_dim)  # Inner Product for Cosine Similarity
        self.bm25: BM25Okapi = None
        self.corpus: List[Dict[str, Any]] = []
        # Local Cross-Encoder for high-precision final re-scoring
        self.reranker = CrossEncoder("BAAI/bge-reranker-base")

    def build_indexes(self, chunks: List[Dict[str, Any]], embeddings: np.ndarray):
        """Constructs both FAISS dense index and BM25 token corpus."""
        self.corpus = chunks
        faiss.normalize_L2(embeddings)
        self.dense_index.add(embeddings)

        tokenized_corpus = [chunk["text"].lower().split() for chunk in chunks]
        self.bm25 = BM25Okapi(tokenized_corpus)

    def retrieve(self, query: str, query_emb: np.ndarray, top_k: int = 5, candidate_pool: int = 25) -> List[Dict[str, Any]]:
        # 1. Dense Semantic Retrieval
        q_norm = query_emb.reshape(1, -1).copy()
        faiss.normalize_L2(q_norm)
        _, dense_indices = self.dense_index.search(q_norm, candidate_pool)

        # 2. Sparse Lexical BM25 Retrieval
        tokenized_query = query.lower().split()
        bm25_scores = self.bm25.get_scores(tokenized_query)
        bm25_indices = np.argsort(bm25_scores)[::-1][:candidate_pool]

        # 3. Reciprocal Rank Fusion (RRF)
        rrf_scores: Dict[int, float] = {}
        for rank, idx in enumerate(dense_indices[0]):
            rrf_scores[idx] = rrf_scores.get(idx, 0.0) + (1.0 / (self.rrf_k + rank + 1))

        for rank, idx in enumerate(bm25_indices):
            rrf_scores[idx] = rrf_scores.get(idx, 0.0) + (1.0 / (self.rrf_k + rank + 1))

        # Sort candidate pool by fused RRF rank
        fused_sorted = sorted(rrf_scores.items(), key=lambda x: x[1], reverse=True)[:candidate_pool]

        # 4. Cross-Encoder Deep Reranking
        pairs = [[query, self.corpus[idx]["text"]] for idx, _ in fused_sorted]
        rerank_scores = self.reranker.predict(pairs)

        # Assemble final results with provenance
        results = []
        ranked_order = np.argsort(rerank_scores)[::-1][:top_k]
        for r_idx in ranked_order:
            original_corpus_idx = fused_sorted[r_idx][0]
            item = self.corpus[original_corpus_idx]
            results.append({
                "chunk_id": item["id"],
                "doc_name": item["source"],
                "page_number": item["page"],
                "content": item["text"],
                "cross_encoder_score": float(rerank_scores[r_idx]),
                "rrf_score": float(fused_sorted[r_idx][1])
            })

        return results
4. User Interface Architecture
DocuAI Studio's frontend is designed for operational workflows rather than simplistic chat bubbles:
Data Lake Management
Drag-and-drop batch upload supporting PDF, DOCX, XLSX, and web crawler scrapers with live parsing progress and token count counters.
Document Comparator
Side-by-side semantic alignment highlighting clause modifications across vendor contracts, versions, or regulatory updates.
Knowledge Graph Visualization
Interactive force-directed graph mapping extracted named entities (organizations, monetary values, dates) and their relational edges.
Active Vector Index Registry
Real-time index health monitor displaying embedding dimension statistics, cluster distribution, and memory utilization.
5. Production API Surface
DocuAI exposes 40+ REST and WebSocket endpoints organized across 6 domain routers in FastAPI:
| Method & Path | Category | Description |
|---|---|---|
POST /api/v1/ingest/upload |
Ingestion | Multipart asynchronous file upload with OCR fallback parsing |
POST /api/v1/query/hybrid |
Retrieval | Dual-track FAISS + BM25 search with RRF scoring |
POST /api/v1/query/stream |
Generation | WebSocket / SSE streaming answer generation with verified citations |
POST /api/v1/compare/diff |
Document AI | Semantic clause-by-clause difference analysis between two docs |
GET /api/v1/graph/entities |
Knowledge Graph | Extracts structured entity nodes and relationship triplets |
GET /api/v1/metrics/analytics |
Observability | Query latency percentiles, hit rates, and token consumption logs |
6. Retrieval & Latency Benchmarks
We benchmarked DocuAI Studio v3.1 across an enterprise financial dataset (1,200 annual reports, 85,000 text chunks) comparing pure dense retrieval, pure BM25, and our two-stage hybrid cascade:
7. Key Engineering Challenges Solved
Lossless Extraction of Markdown Tables
Standard PDF extractors flatten tables into single lines, mixing column headers with data cells. We engineered an adaptive layout engine using PyMuPDF and pdfplumber that detects table borders, formats tabular regions into clean GitHub-flavored Markdown tables, and preserves column headers across split-page chunks.
Cross-Encoder Inference Latency Optimization
Running a BERT-scale Cross-Encoder over 50 candidate chunks took >1,800ms on CPU. We quantized bge-reranker-base to ONNX INT8 with OpenVINO runtime, reducing reranking latency to 110ms for 25 candidate pairs without loss of ranking fidelity.
Local vs Cloud LLM Provider Agnosticism
Enterprises require running private models (via Ollama / vLLM) for sensitive legal documents while using cloud APIs (OpenAI GPT-4o, Anthropic Claude 3.5) for broad summaries. We implemented an abstract LLM interface layer that dynamically negotiates prompt formatting, token streaming, and function calling across both targets.
Zero-Downtime Index Swapping
When ingesting new document batches, rebuilding the FAISS and BM25 indexes previously blocked active search queries. We implemented a double-buffered atomic pointer swap in memory, allowing read queries to hit the active index while a background worker compiles the new snapshot.
8. Production Takeaways & Code Access
DocuAI Studio v3.1 demonstrates that RAG system quality is won or lost in the retrieval pipeline before the LLM generates a single token. By replacing naive vector search with a principled, layered hybrid cascade and treating documents as structured data objects, teams can deploy trustworthy Document AI platforms that deliver transparent, verifiable business outcomes.
- Stack
- FastAPI, LangChain, FAISS, BM25, SentenceTransformers, Ollama, Docker, HTML5/CSS3
- Key Techniques
- Reciprocal Rank Fusion (RRF), Cross-Encoder Reranking, Markdown Table Extraction