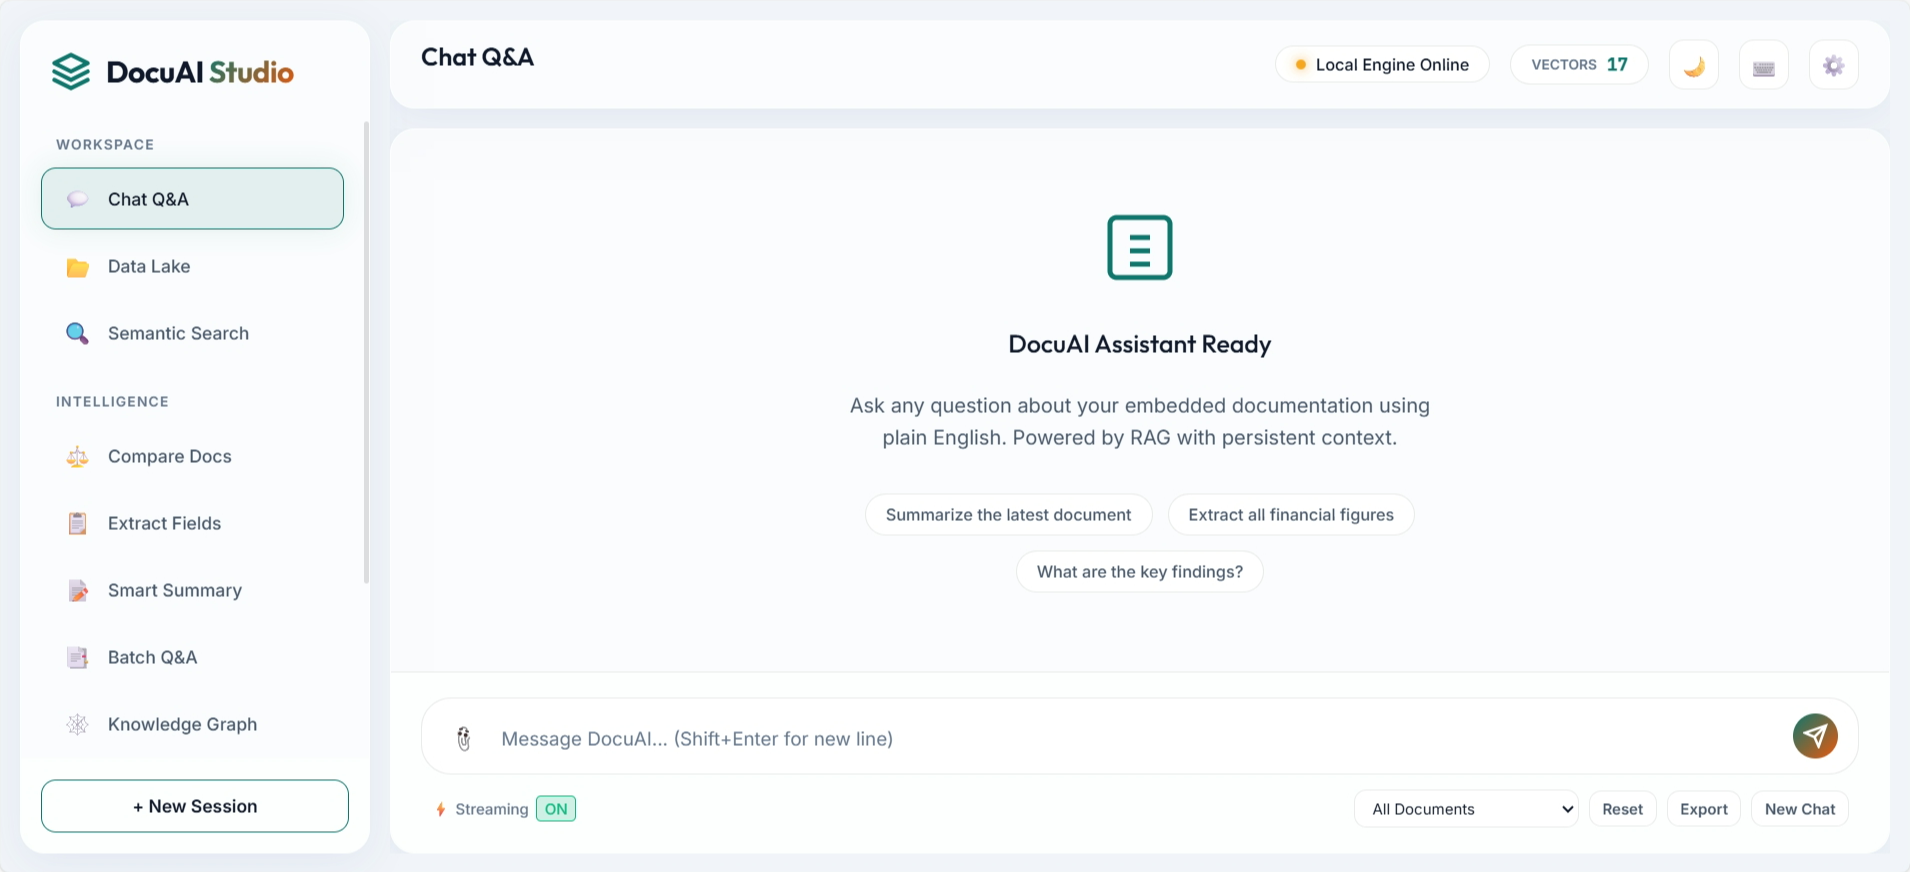
Production RAG: FAISS, BM25 & Reciprocal Rank Fusion
Building a production-grade RAG pipeline from scratch: dense embeddings, BM25 lexical search, RRF rank fusion, cross-encoder reranking, and quantitative Ragas hallucination evaluation.
Production guides on building reliable LLM systems: hybrid dense/sparse RAG cascades, cyclic LangGraph state machines, deterministic guardrails, and enterprise Document AI platforms.
Building enterprise Generative AI requires treating language models as reasoning primitives within deterministic software harnesses. Reliable production applications demand structured JSON schemas, cyclical state graphs with human-in-the-loop checkpoints, and hybrid vector/lexical retrieval evaluated through quantitative metrics like Ragas. Explore the engineering blueprints below.
Building a production-grade RAG pipeline from scratch: dense embeddings, BM25 lexical search, RRF rank fusion, cross-encoder reranking, and quantitative Ragas hallucination evaluation.
13 min
Full-stack engineering teardown: multi-format async parsing, FAISS + BM25 hybrid indexing, cross-encoders, and local-first LLM orchestration across 40+ FastAPI endpoints.
Architecting cyclical multi-agent workflows: state schema design, conditional routing, checkpoint persistence, and Human-in-the-Loop validation gates.
Engineering a multi-agent decision intelligence platform powered by Gemini 2.5 and Vertex AI to synthesize municipal telemetry and simulate digital twin policy outcomes.
Tracing the architectural evolution from Transformer self-attention to LoRA fine-tuning, vLLM high-throughput serving, and tool-augmented agent loops.
Fine-tuning localized language models with clinical triage guardrails, differential privacy guarantees, and crisis risk classification thresholds.